Practice ASoftware
Custom AI Development
Agents, copilots, search and extraction built around one real workflow in your business, measured against an evaluation set we write with your team.
Explore custom AI →AI that never leaves the building.
LLM.co builds private LLMs and the custom AI systems that run on them, on infrastructure you control: your rack, your cloud account, or a network with no way out. Your data stays home.
Most firms do one half. Consultancies build on public APIs and leave. Infrastructure vendors sell boxes with nothing useful on them. LLM.co does the software and the deployment, so the system that passes the demo is the one that passes the security review.
Agents, copilots, search and extraction built around one real workflow in your business, measured against an evaluation set we write with your team.
Explore custom AI →
A private LLM on open-weight models, served on hardware you own or a cloud tenancy you control, with access control and audit logs your compliance team already understands.
A private LLM is a large language model that runs on infrastructure you control. The model weights, your prompts, your documents and the logs stay on your own servers, in your own cloud account or on an air-gapped network. Nothing is sent to an outside model provider, and nothing is used to train someone else's model.
LLM.co builds every private LLM on open-weight models such as Llama, Qwen, Mistral and gpt-oss. You hold a copy of the weights, you choose when to upgrade, and the model keeps working if a vendor changes its terms, its prices or its catalog.
A private LLM on your own hardware is only useful once it is connected to your data and your workflow. Custom AI development is the work of building that system around one specific job in your business. It reads your records, follows your rules and writes its output into the systems your staff already use, such as the ERP, CRM, claims platform or document management system.
A custom system built on a public API often fails the security review before launch. A private LLM with nothing built on it sits idle. Doing both in one engagement avoids each problem: the system that wins the demo is the same private LLM deployment that clears your security review.
A private LLM suits organizations whose most useful data is also their most sensitive. That includes law firms and legal departments, healthcare providers, banks and insurers, government and defense contractors, manufacturers, utilities and professional services firms. It also suits any company whose contracts or policies forbid sending client data to a third party.
It makes financial sense once usage is broad and steady. Per-seat and per-token fees grow with every user. A private LLM on dedicated hardware has a fixed cost that does not.
The same private LLM deployment ships to three places. On-premises, it runs on GPU servers in your own data center. In your cloud account, it runs on dedicated GPUs in AWS, Azure or GCP under your keys and network rules. Air-gapped, it runs with no internet route at all and takes updates on signed media.
Every private LLM we deploy ships with single sign-on, document-level permissions and audit logging to your SIEM before wide release, so private AI fits the controls your security team already runs.
Engagements start with a two-week discovery sprint to rank use cases, check the data and model the cost of a private LLM against your current API spend. A focused first system usually reaches production in eight to twelve weeks. Every phase ends with a go / no-go decision, and you own the code, prompts, evaluation sets and any trained weights.
You own the code, the prompts, the evaluation sets and any weights we train. No platform fee, no per-seat license, no lock-in to us.
Multi-step agents that read, decide and act inside your systems, with a human approval step wherever you want one.
Ask questions across contracts, SOPs, tickets and drives. Every answer cites the source page and respects document permissions.
Purpose-built copilots and internal tools with the UI, permissions and data connections one team actually needs.
Open-weight models adapted to your terminology, formats and tone, then distilled to run on smaller hardware.
Extraction, classification and checking for scans, handwriting, forms, drawings and photos, with confidence scores per field.
Connectors into the systems of record you already run, so AI output lands where work happens instead of in a chat window.
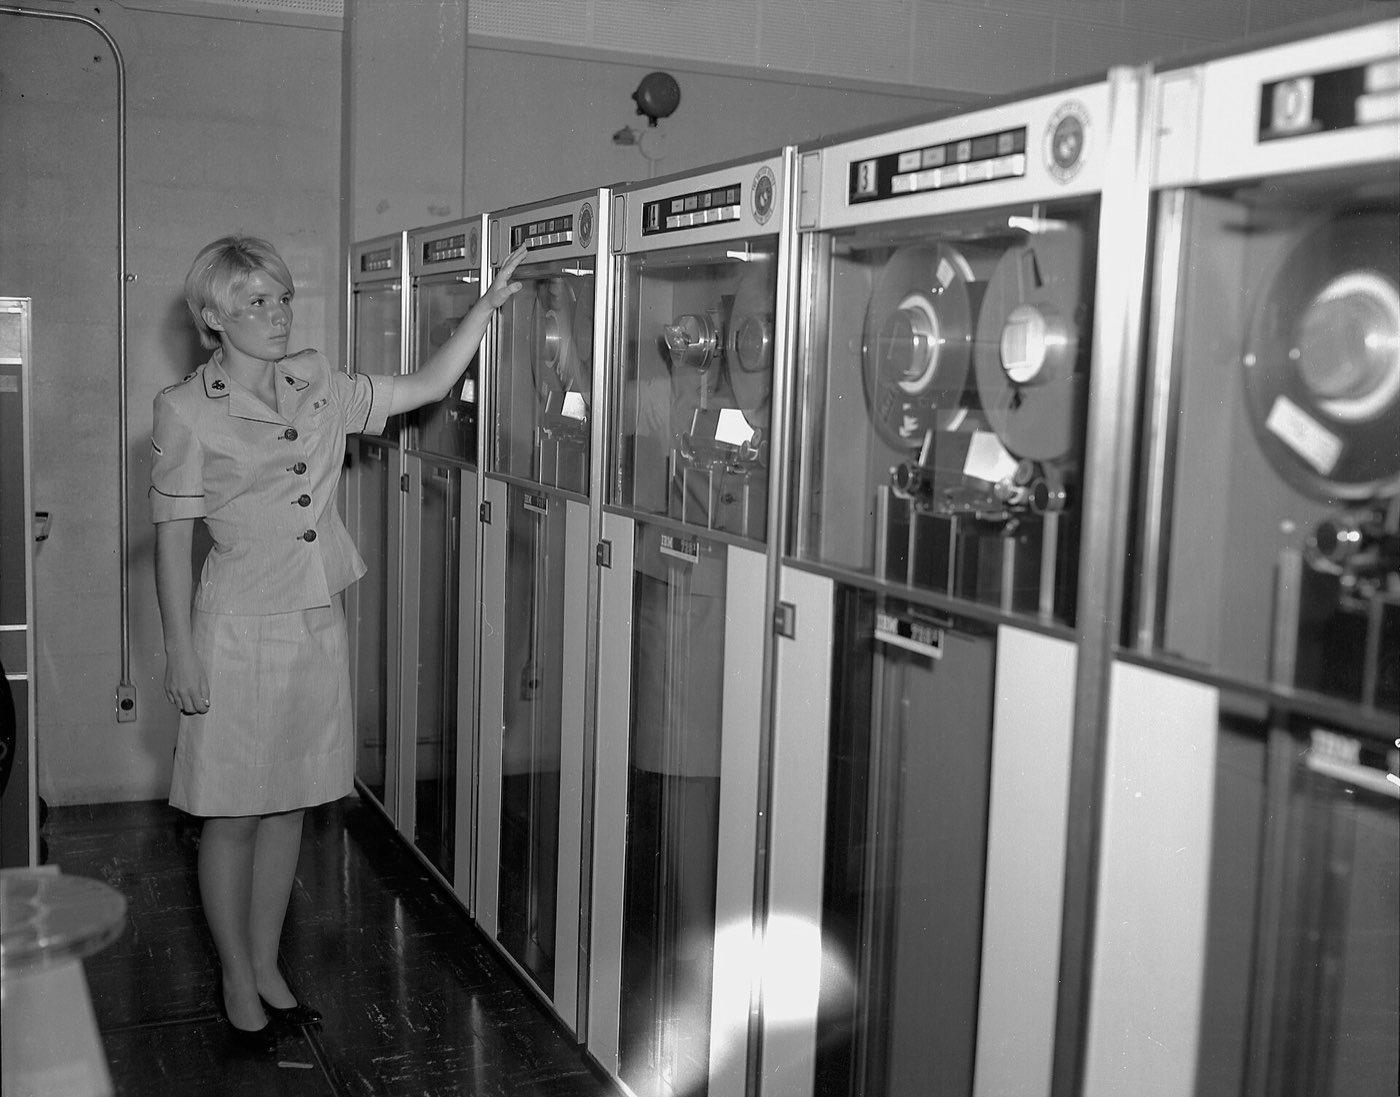
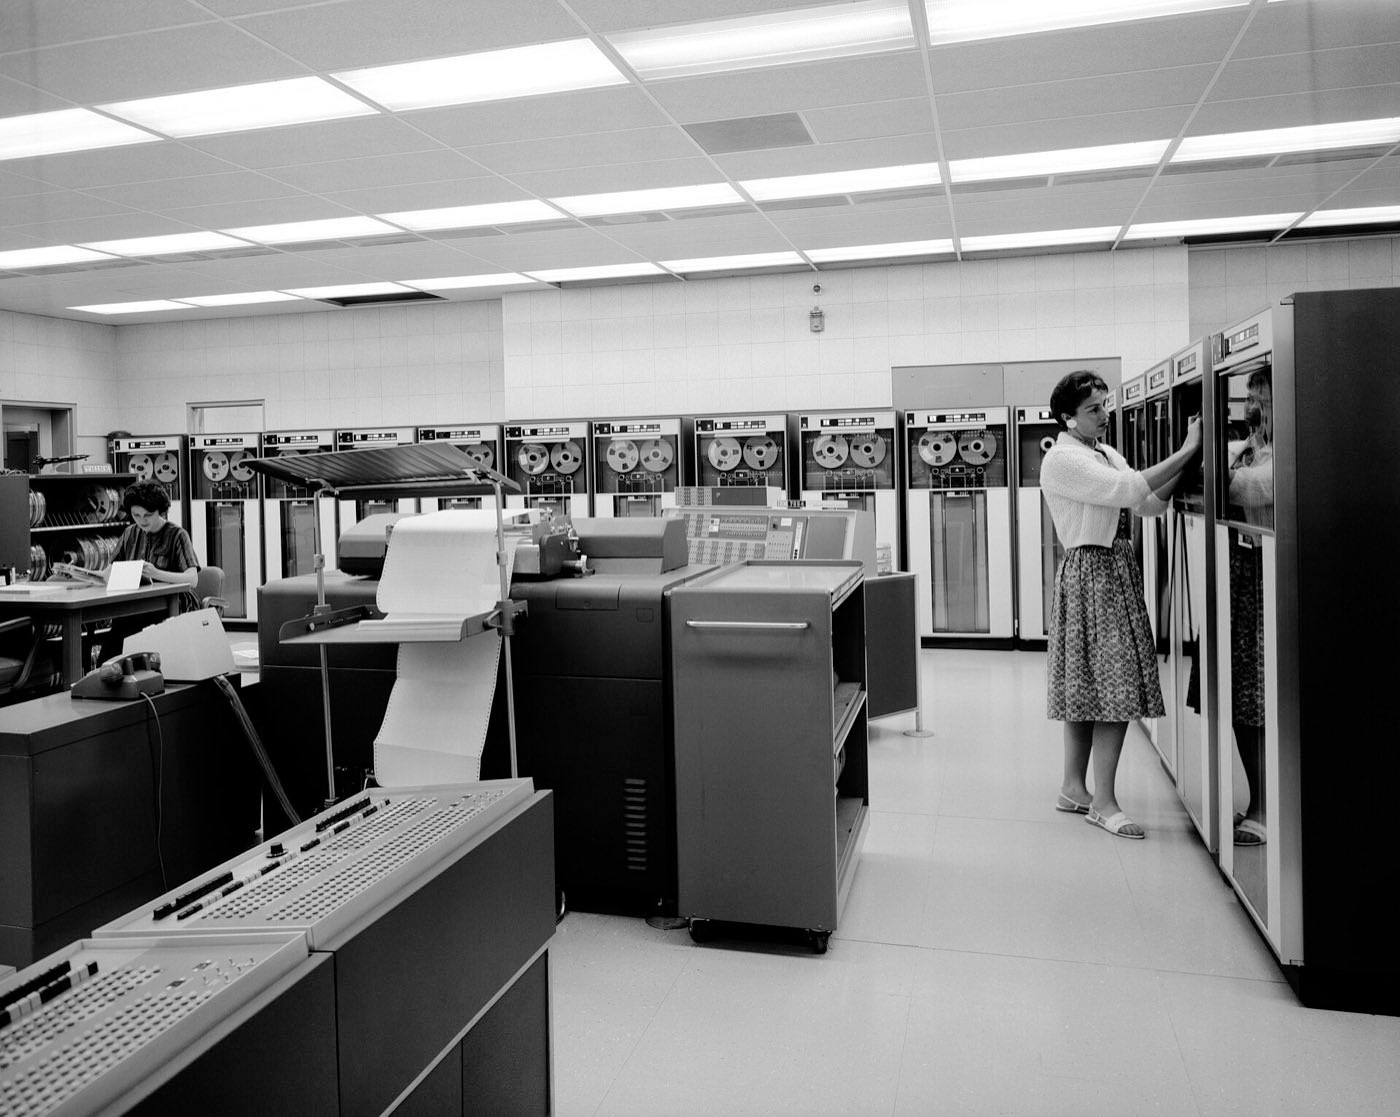
In 1958 nobody shipped NASA's data to someone else's computer. The machine was in the room. Public AI reversed that: prompts, files and customer records now travel to a vendor's GPUs. A private LLM puts the computer back where your data is.
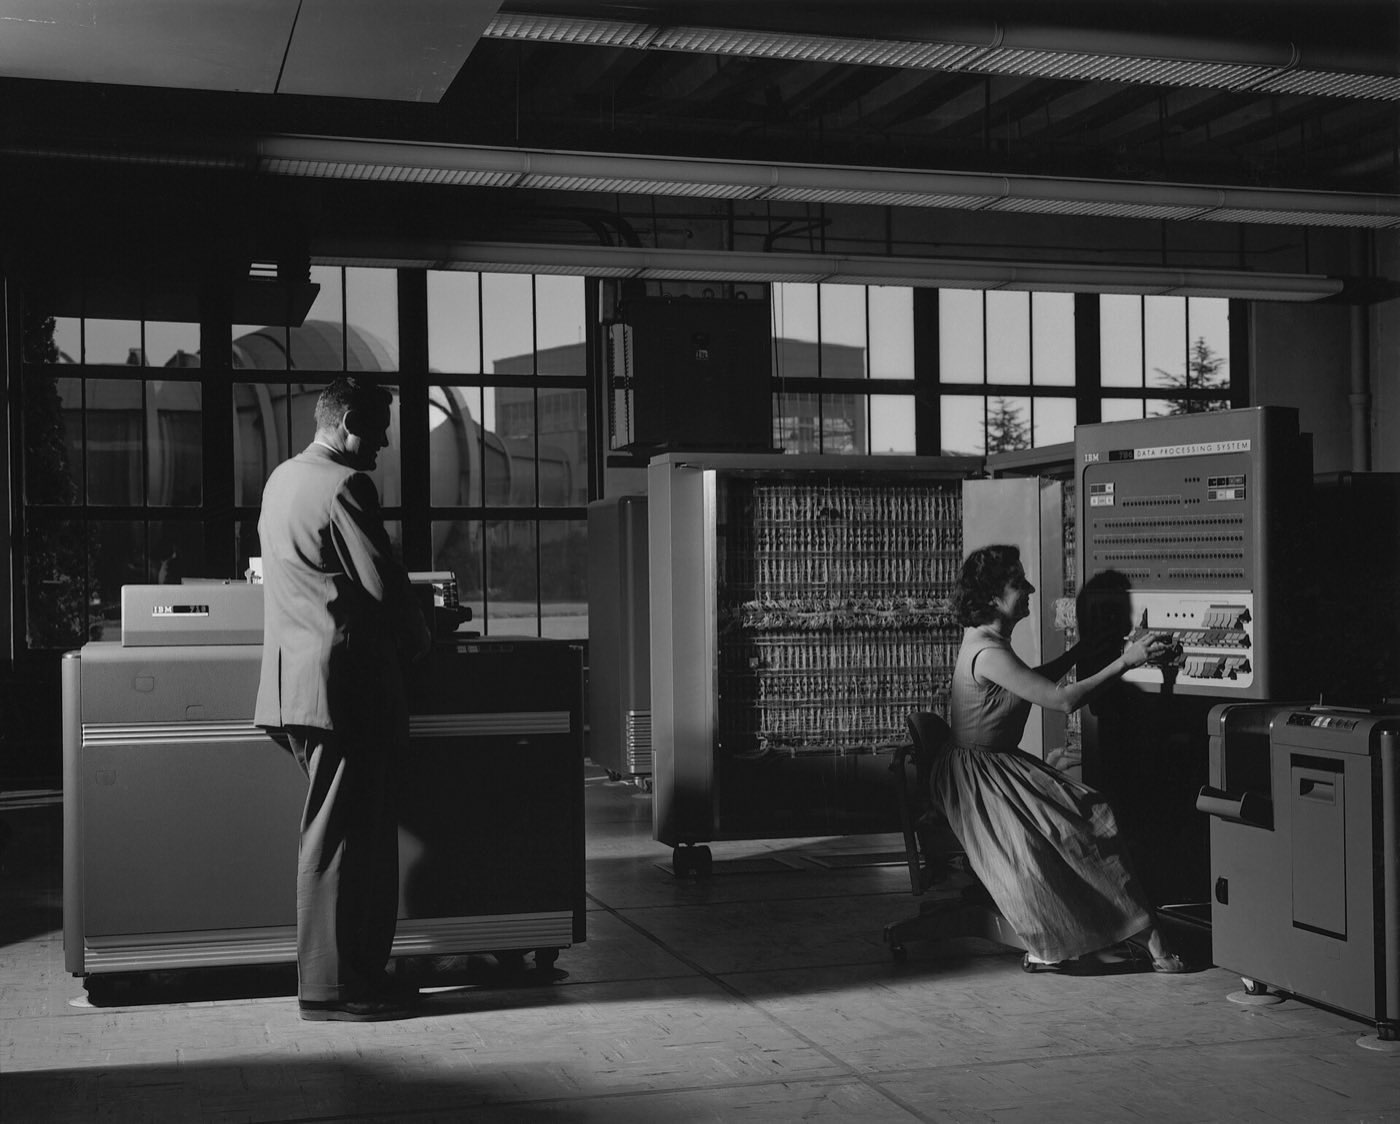
The computer is a room you can walk into. Every byte stays inside it.
AI arrives as an API. Your data leaves to reach it, and you rent the model by the token.
Open-weight models handle most business work well. The computer comes back inside.
Same rule as the mainframe era: the data stays with the people responsible for it.
See where it can run →Fixed-scope phases with a go / no-go at the end of each one. You can stop after any phase and keep everything built so far. How we work
Pick the workflow worth automating and prove the numbers.
A working build on your real data, scored against an eval set.
Make it safe to give to hundreds of people and an auditor.
Installed on your hardware or in your cloud account.
Monitoring, model upgrades and retraining as the work changes.
Public model APIs are a fine place to experiment. For regulated data, client files and anything you would not email to a stranger, here is what changes.
| Public AI API | LLM.co private LLM | |
|---|---|---|
| Where prompts go | The vendor's servers | Your network. Nowhere else. |
| Who holds the weights | The vendor | You. Copied to your storage. |
| Model choice | The vendor's catalog, changed on their schedule | Any open-weight model, pinned until you upgrade |
| Cost shape | Per token, rises with every new user | Fixed hardware or reserved GPU, flat at scale |
| Audit trail | The vendor's logs, on request | Every call in your SIEM, retained by your policy |
| Works offline | No | Yes. Air-gap ready. |
The same private LLM ships to any of these targets. Start in your cloud account, move on-prem when volume justifies the hardware.
A private LLM matters most where data is regulated, privileged or simply too valuable to hand over. That is most of our work.
Contract review and clause search on the firm's own precedent.
HIPAA · PHI · BAAChart summaries and prior-auth packets that stay on the network.
GLBA · SOX · FINRALoan file extraction, KYC review, research on internal data.
CMMC · ITAR · FedRAMPAir-gapped assistants for controlled environments.
Trade secrets · OT · ITARMaintenance and quality assistants trained on your manuals.
NAIC · State DOI · PIIClaims intake, triage and underwriting memos from the full file.
NERC CIP · OT · Critical infrastructureField procedure search and outage reporting at the edge.
Client NDAs · Independence · ConfidentialityFirm knowledge bases that respect client walls.
A private LLM is a large language model that runs entirely on infrastructure you control: your own servers, your own cloud account or an air-gapped network. Your prompts and documents never reach a third-party model provider, and no outside company can use your data to train its models.
With a public API, every prompt and file travels to the vendor's servers and you rent the model by the token. With a private LLM, the model runs inside your network, you hold the weights, every call is logged to your own SIEM, and the cost is fixed hardware or reserved GPUs instead of per-token fees.
It is the design and build of an AI system for one specific workflow in your business, running on your private LLM. Examples include agents that act inside your ERP, search across your contracts and policies, and models fine-tuned on your own records. Each system is scored against an evaluation set built from your real past cases.
For most business work, yes. Extraction, search, summarization, drafting and agent tasks on your own data run well on current open-weight models. We run a bake-off against your evaluation set in the Prototype phase, so you see the scores for each candidate before you commit to hardware.
No. Most clients start with a private LLM on dedicated GPUs in their own cloud account and move on-premises once usage is steady. During discovery we size both options and show the month when owned hardware breaks even against cloud rental.
You do. Source code, prompts, evaluation sets, fine-tuned weights and infrastructure code are delivered to your repositories. There is no platform license and no per-seat fee. If you stop working with us after any phase, you keep everything built up to that point.
The discovery sprint is a fixed fee. Builds are quoted one phase at a time after discovery, so you never sign for more than the next step. Cost depends mostly on the number of integrations, the condition of your data, your approval and audit requirements, and where the private LLM will run.
The discovery sprint takes two weeks. A focused first system usually reaches production in eight to twelve weeks after that. The build runs as Prototype in three to four weeks, Harden in four to six, and Deploy in one to two. Integrations and internal review cycles affect where a project lands.
It is built to fit your existing controls. Users sign in through your identity provider, permissions mirror your source systems, data stays on infrastructure you control and every action is logged to your SIEM. We document data flows so your private LLM can support your HIPAA, GLBA, SOC 2 or CMMC program.
Tell us the workflow and where the data lives. An engineer, not a salesperson, replies within one business day with a first take on architecture and cost.