LLM.co · Private AI with Custom AI DevelopmentPrivate AI
Open-weight models on hardware you own, a cloud account you control, or a network with no route out. Prompts, documents, weights and logs stay with you.
Where it runs, and how it's governed.
Pick a deployment target; governance comes with every one.
Know where your prompts go.
Public model APIs are a fine place to experiment. For regulated data, client files and anything you would not email to a stranger, here is what changes.
| Public AI API | LLM.co private AI | |
|---|---|---|
| Where prompts go | The vendor's servers | Your network. Nowhere else. |
| Who holds the weights | The vendor | You. Copied to your storage. |
| Model choice | The vendor's catalog, changed on their schedule | Any open-weight model, pinned until you upgrade |
| Cost shape | Per token, rises with every new user | Fixed hardware or reserved GPU, flat at scale |
| Audit trail | The vendor's logs, on request | Every call in your SIEM, retained by your policy |
| Works offline | No | Yes. Air-gap ready. |
What private AI means in practice
Private AI is an AI system where the model, the prompts, the documents it reads and the logs it writes all sit on infrastructure your organization controls. The model is an open-weight model, so the weights are files on your storage. Your team can inspect them, pin a version and keep running it for as long as it serves the work.
That is a stricter standard than an enterprise subscription with a no-training clause. A subscription still sends each request to a vendor's servers, under the vendor's retention policy and release schedule. With a private LLM, requests stay on your network, and the model changes only when your team approves the change.
When private AI is the right choice
Private AI is worth the extra engineering when at least one of these is true for your organization.
If none of them apply and volume is low, a public API is often the sensible place to start. We say so during the discovery sprint.
- The data is regulated or contractually restricted, such as PHI, CUI, client files or nonpublic financial records.
- Data sovereignty rules pin data to a country, a region or a single building.
- Usage is steady and broad enough that fixed GPU capacity costs less than per-token pricing.
- The system has to run with no internet connection, in an enclave, on a plant floor or at a field site.
- Audits or validation require a model version that stays fixed.
Three deployment targets on one architecture
LLM.co builds every private AI system on the same stack, whether it runs on-premises, in your cloud account or behind an air gap. Open-weight models are served with vLLM on dedicated GPUs. A gateway in front of them exposes one OpenAI-compatible API with keys, quotas, routing and audit logging. Retrieval indexes, agent tools and application code run as containers beside it.
Because the stack is the same everywhere, a system can start in a private cloud account and move to your own GPU servers later with little change. The choice of target comes down to procurement, regulation and where your data already lives.
How we size hardware for a private LLM
Sizing starts with the work. We take the models that won the bake-off on your evaluation set, the number of concurrent users, typical context lengths and batch volumes, and turn them into GPU memory, server count and storage. Quantization often lets a model fit on fewer or smaller GPUs with no meaningful change in evaluation scores.
Options range from a single server with RTX 6000 or L40S cards for one department to multi-node clusters on NVIDIA H100, H200 or AMD MI300X for organization-wide use. Specs are vendor-neutral, and we work with the reseller or cloud provider you already use.
Security and governance come with every build
Every deployment ships with single sign-on through Okta or Microsoft Entra ID, role- and document-level access, and structured logs of each prompt, retrieved passage, answer and action sent to your SIEM. Monitoring runs inside your environment. The controls are designed to support the SOC 2, HIPAA, GLBA or CMMC program you already run, and we provide the architecture and data-flow documentation your reviewers ask for.
What you receive
Private AI from LLM.co comes paired with custom AI development, so the infrastructure arrives with a working system on top of it. You own all of it, with no platform license.
- Application source code, prompts and evaluation sets in your repositories
- Infrastructure code, container images and any trained weights on your storage
- Runbooks, dashboards and alerts for your operations team
- Architecture, data-flow and control documentation for your security review
Pick the room it runs in.
The same system ships to any of these targets. Start in your cloud account, move on-prem when volume justifies the hardware.
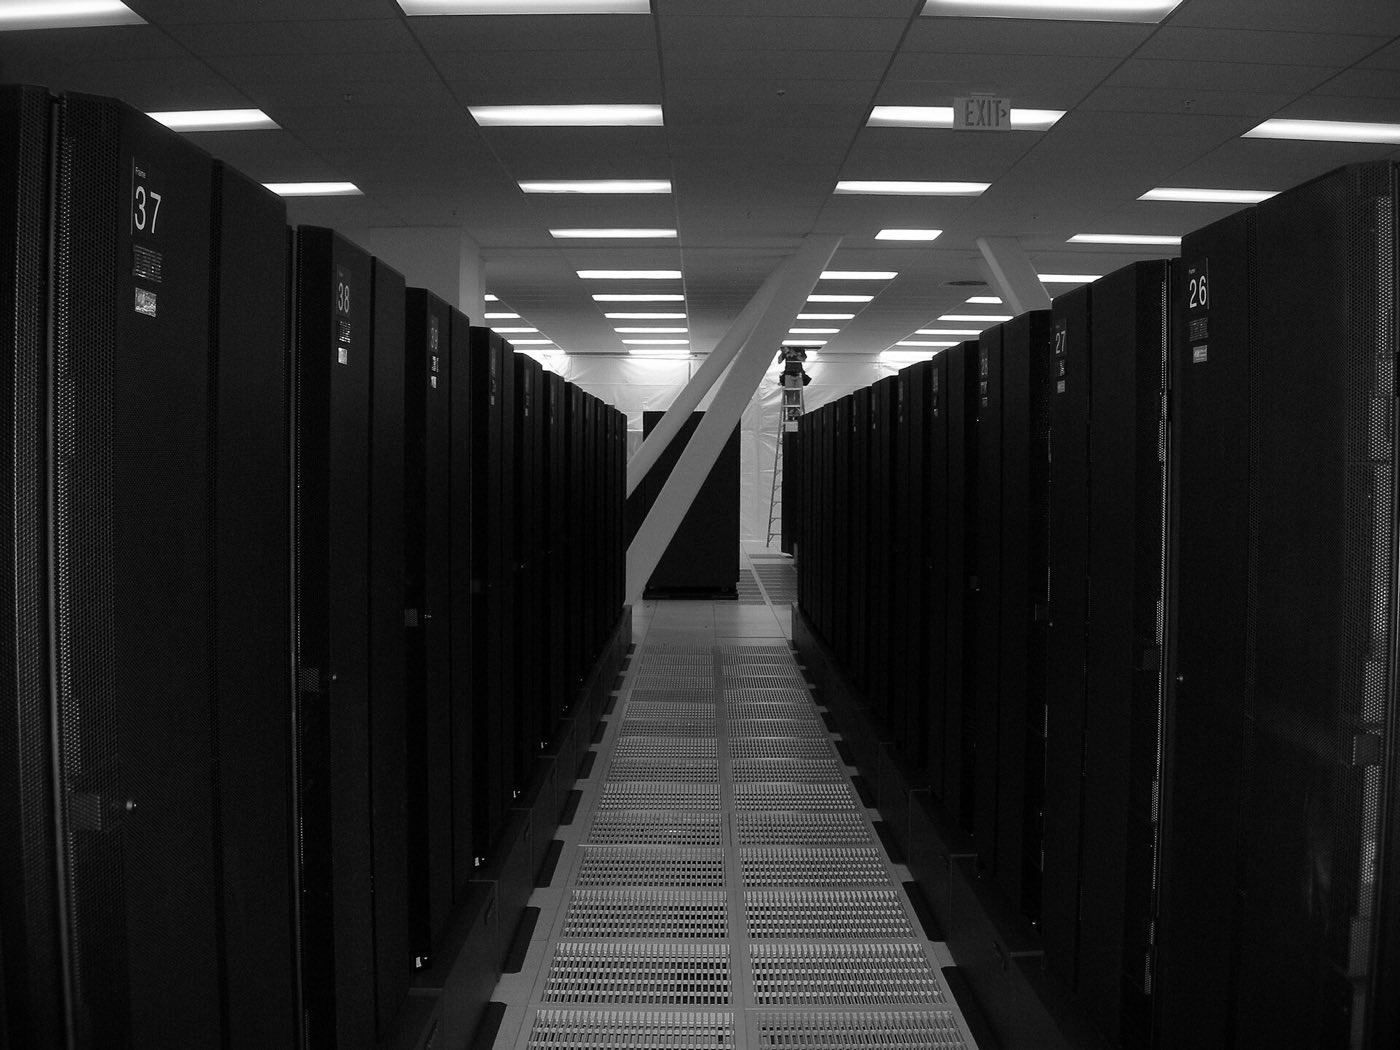
Computing used to live in the building.
In 1958 nobody shipped NASA's data to someone else's computer. The machine was in the room. Public AI reversed that: prompts, files and customer records now travel to a vendor's GPUs. We put the computer back where your data is.
The computer is a room you can walk into. Every byte stays inside it.
AI arrives as an API. Your data leaves to reach it, and you rent the model by the token.
Open-weight models handle most business work well. The computer comes back inside.
Same rule as the mainframe era: the data stays with the people responsible for it.
See where it can run →Asked on every scoping call.
What is private AI?
Private AI is an AI system where the models, prompts, documents and logs all stay on infrastructure you control, such as your own servers, your own cloud account or an air-gapped network. It runs on open-weight models whose weights you hold, and nothing is sent to a third-party model provider unless you decide it may be.
What is the difference between private AI and an enterprise AI subscription?
An enterprise subscription still runs on the vendor's infrastructure, under the vendor's retention policy and model release schedule. Private AI runs on infrastructure you control, with open-weight models you can inspect, pin and keep. Your security team sets the network rules, holds the logs and decides when a model changes.
Which models can run as private AI?
Open-weight families such as Llama, Qwen, Mistral, DeepSeek, Gemma and gpt-oss, plus speech and embedding models. We choose by bake-off against an evaluation set built from your own cases, so you see accuracy, speed and hardware needs for each candidate before committing to one.
Are open-weight models good enough for business work?
For most business work, yes. Extraction, search, summarization, drafting and agent tasks on your own data are well within their range. We run the bake-off during the prototype phase, so you see the scores on your real documents before you commit to hardware or a deployment target.
How much does private AI cost?
Cost depends on model size, user count, volume and deployment target. At low volume a public API is usually cheaper. Once usage is steady and broad, owned hardware or reserved GPUs usually cost less than per-token pricing. We model your expected volumes and show the break-even month before you commit.
What hardware does a private LLM need?
It depends on the model, the number of concurrent users and context lengths. A single server with RTX 6000 or L40S cards can serve one department. Larger rollouts use NVIDIA H100 or H200, or AMD MI300X. Many clients start on dedicated GPUs in their own cloud account and buy hardware later.
Is private AI more secure than a public AI API?
It removes a third party from the data path. Prompts, documents and logs stay inside your network, under your identity provider, encryption keys and SIEM. Security still depends on how the system is built, so every deployment includes SSO, role- and document-level access, audit logging and a documented security review.
Can we start in the cloud and move on-premises later?
Yes. The system ships as containers and infrastructure code with the same gateway in every environment, so moving from your cloud account to your own GPU servers is a deployment change. The applications, models and evaluation sets carry over as they are.
Submit a job card.
Tell us the workflow and where the data lives. An engineer, not a salesperson, replies within one business day with a first take on architecture and cost.