Choosing Between Fine-Tuning, RAG, and Agentic AI for Enterprise Workloads
Fine-tuning, RAG, and agentic AI solve different enterprise problems. Use this decision framework to match each architecture to workload, risk, and your data.

Which approach should a regulated enterprise build first — RAG, fine-tuning, or an agentic system? Pick by the shape of the workload, not the shape of the vendor pitch. The three are composable layers, not alternatives: RAG grounds answers in current knowledge, fine-tuning shapes how the model talks, and agents execute multi-step actions against tools and data. The hard part is knowing which layer a given workload actually needs, and in what order to add the others.
Adoption patterns bear this out. A Menlo Ventures 2024 survey found RAG at 51% of production implementations, up from 31% the year before, fine-tuning at 9%, and agentic architectures at 12%. The split is not a popularity contest. It reflects what each layer solves cheaply, and a sober decision framework starts from the workload and adds layers only where they earn their keep.
Three Layers That Do Different Jobs
Retrieval-augmented generation pulls fresh context into the prompt at inference time. The foundational RAG paper from Facebook AI Research, UCL, and NYU, submitted in May 2020, combined a pre-trained seq2seq model with a dense vector index of Wikipedia reached by a neural retriever. The pattern maps cleanly onto the enterprise problem: knowledge that changes weekly — policy updates, case files, pricing, incident tickets — does not belong baked into model weights. It belongs in a vector store the model reads at runtime.
Fine-tuning changes weights. It teaches a base model a house style, a vocabulary, a compliance tone, or a classification schema that will not change often. For most enterprise shops, parameter-efficient methods are the default. The LoRA paper showed that low-rank adaptation can reduce trainable parameters by 10,000x and GPU memory requirements by 3x versus full fine-tuning of GPT-3 175B with Adam, with no additional inference latency. That changes the economics of specialization from a capital project into a bounded engineering task.
Agentic systems add action. The model plans, calls tools, inspects results, retries, and commits. This is where the risk surface grows fastest and where private AI agents start to earn their isolation. An agent reads a chart of accounts, writes a journal entry, files a ticket, or issues an API call that moves money. Whatever sits behind those tool calls is now part of the model's attack surface.
Where Each Layer Actually Fits
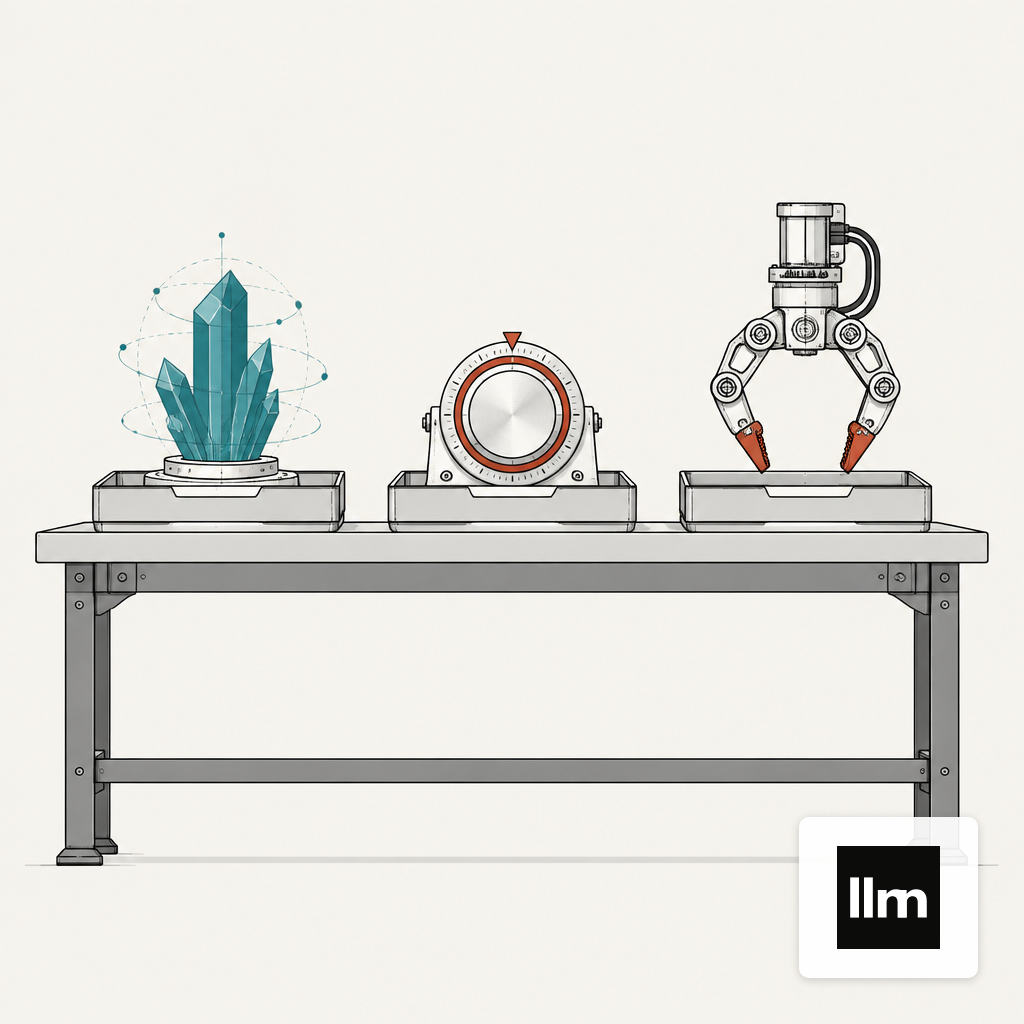
The decision rarely reduces to one approach. A sharper question is which layer answers the most pressing workload constraint. If the top complaint is stale answers, retrieval goes first. If the complaint is that outputs sound wrong (wrong register, wrong format, wrong compliance posture), behavior shaping comes first. If the complaint is that a person still has to wire together six systems to finish a task, autonomous action comes first.
The three approaches occupy different parts of a single trade-off map. RAG favors workloads where knowledge churns daily and decisions can be defended with citations. Fine-tuning favors workloads where patterns repeat and the cost of restating them in every prompt adds up over millions of calls. Agents favor workloads with branching, tool-heavy steps that a human would otherwise do by hand. Reading that map against a specific workload is the first real design decision, and the isolation requirements for agentic deployments are not optional in regulated settings.
Sequencing Builds Beats Betting on One
Stanford's 2025 AI Index Report found 78% of organizations reported using AI in 2024, up from 55% the year before. Moving from "using AI" to "running production workloads with audit trails" is what burns budget. Sequencing contains the cost.
A workable order for regulated deployments:
- Ground first. Stand up retrieval against a controlled corpus. Measure hit rate, citation accuracy, and refusal behavior before anything else touches the weights.
- Shape second. Once retrieval is stable, fine-tune only if generic base-model output still misses house style, format, or domain classification at a rate the business will not tolerate.
- Act third. Add tool calls when the human handoff is the bottleneck, not before. Limit the first agent to read-only tools until the audit log is proven.
Skipping ground-first is the most common and most expensive mistake. Fine-tuning a model to compensate for missing retrieval bakes stale facts into weights that then have to be retuned every time those facts move.
Cost and Latency Math
The three layers price differently. RAG adds vector-store storage, embedding costs, and retrieval latency on every call. Fine-tuning front-loads compute into a one-time or periodic training run and leaves inference untouched. Agents multiply token spend because each turn may invoke the model several times before completing, and tool calls carry their own latency tail.
The LoRA figures above sit at the heart of the fine-tuning economics argument. A workload that can be specialized with low-rank adaptation does not require the GPU footprint of a full-weight retraining run, and the same base model can carry several lightweight adapters served from one deployment. For a deeper view of where private deployment dollars actually land, the site's cost breakdown analysis walks the line items.
Audit Implications Compound Fast
Each layer adds a different kind of record to keep. Retrieval logs must capture the documents fetched, the embeddings used, and the version of the index at query time. Fine-tuning requires lineage on the training corpus, the adapter version, and the evaluation set. Agent logs must capture every tool call, every argument, and every outcome, in a form a reviewer can replay end to end.
Regulators have moved. NIST released the AI 600-1 profile on July 26, 2024, as a cross-sectoral companion to the AI Risk Management Framework. Under the EU AI Act, obligations for providers of general-purpose AI models began applying on August 2, 2025. A private deployment architecture that cannot produce a complete retrieval, adapter, and tool-call trail for a given response will not survive a serious conformity assessment.
Picking One for a Specific Workload
Back to the question at the top. A regulated enterprise choosing between RAG, fine-tuning, and agents does not have to choose at all — it has to sequence. Start with the workload complaint. If customer-facing answers are stale, build retrieval and audit the index. If answers sound off against policy, add an adapter trained against a measured eval set. If humans are still gluing systems together after that, scope a single agent with read-only tools and expand its action surface only when the trail holds up. Running the three as layers, on a custom deployment the organization controls, is the architecture that keeps each decision reversible and each audit survivable.
Eric Lamanna is a Digital Sales Manager with a strong passion for software and website development, AI, automation, and cybersecurity. With a background in multimedia design and years of hands-on experience in tech-driven sales, Eric thrives at the intersection of innovation and strategy—helping businesses grow through smart, scalable solutions. He specializes in streamlining workflows, improving digital security, and guiding clients through the fast-changing landscape of technology. Known for building strong, lasting relationships, Eric is committed to delivering results that make a meaningful difference. He holds a degree in multimedia design from Olympic College and lives in Denver, Colorado, with his wife and children.

RAG vs Fine-Tuning vs Long-Context: Choosing the Right Architecture

Fine Tuning Your Open Weights Model for Private LLMs

Fine-Tuning LLMs on Proprietary Data—Without the Cloud

How to Create Human-in-the-Loop Controls for Agentic AI Systems

Choosing Your Open Weights LLM: China vs. U.S.

How to Build a Secure Enterprise RAG Pipeline on PostgreSQL and pgvector
Bringing AI in-house, the right way.
Talk through your private or on-prem LLM deployment with an expert who has shipped them in regulated environments.
Private AI, in your inbox.
Occasional, high-signal notes on enterprise LLM deployment, security, and model strategy. No spam.